Download all files from a web page in one organized run.
When a page mixes PDFs, Office documents, images, ZIPs, CSVs, and hidden fetch responses, manual saving is slow. Grab All Files scans the page, lists detectable files with metadata, and lets you choose exactly what to keep.
Download files from a page in the extension
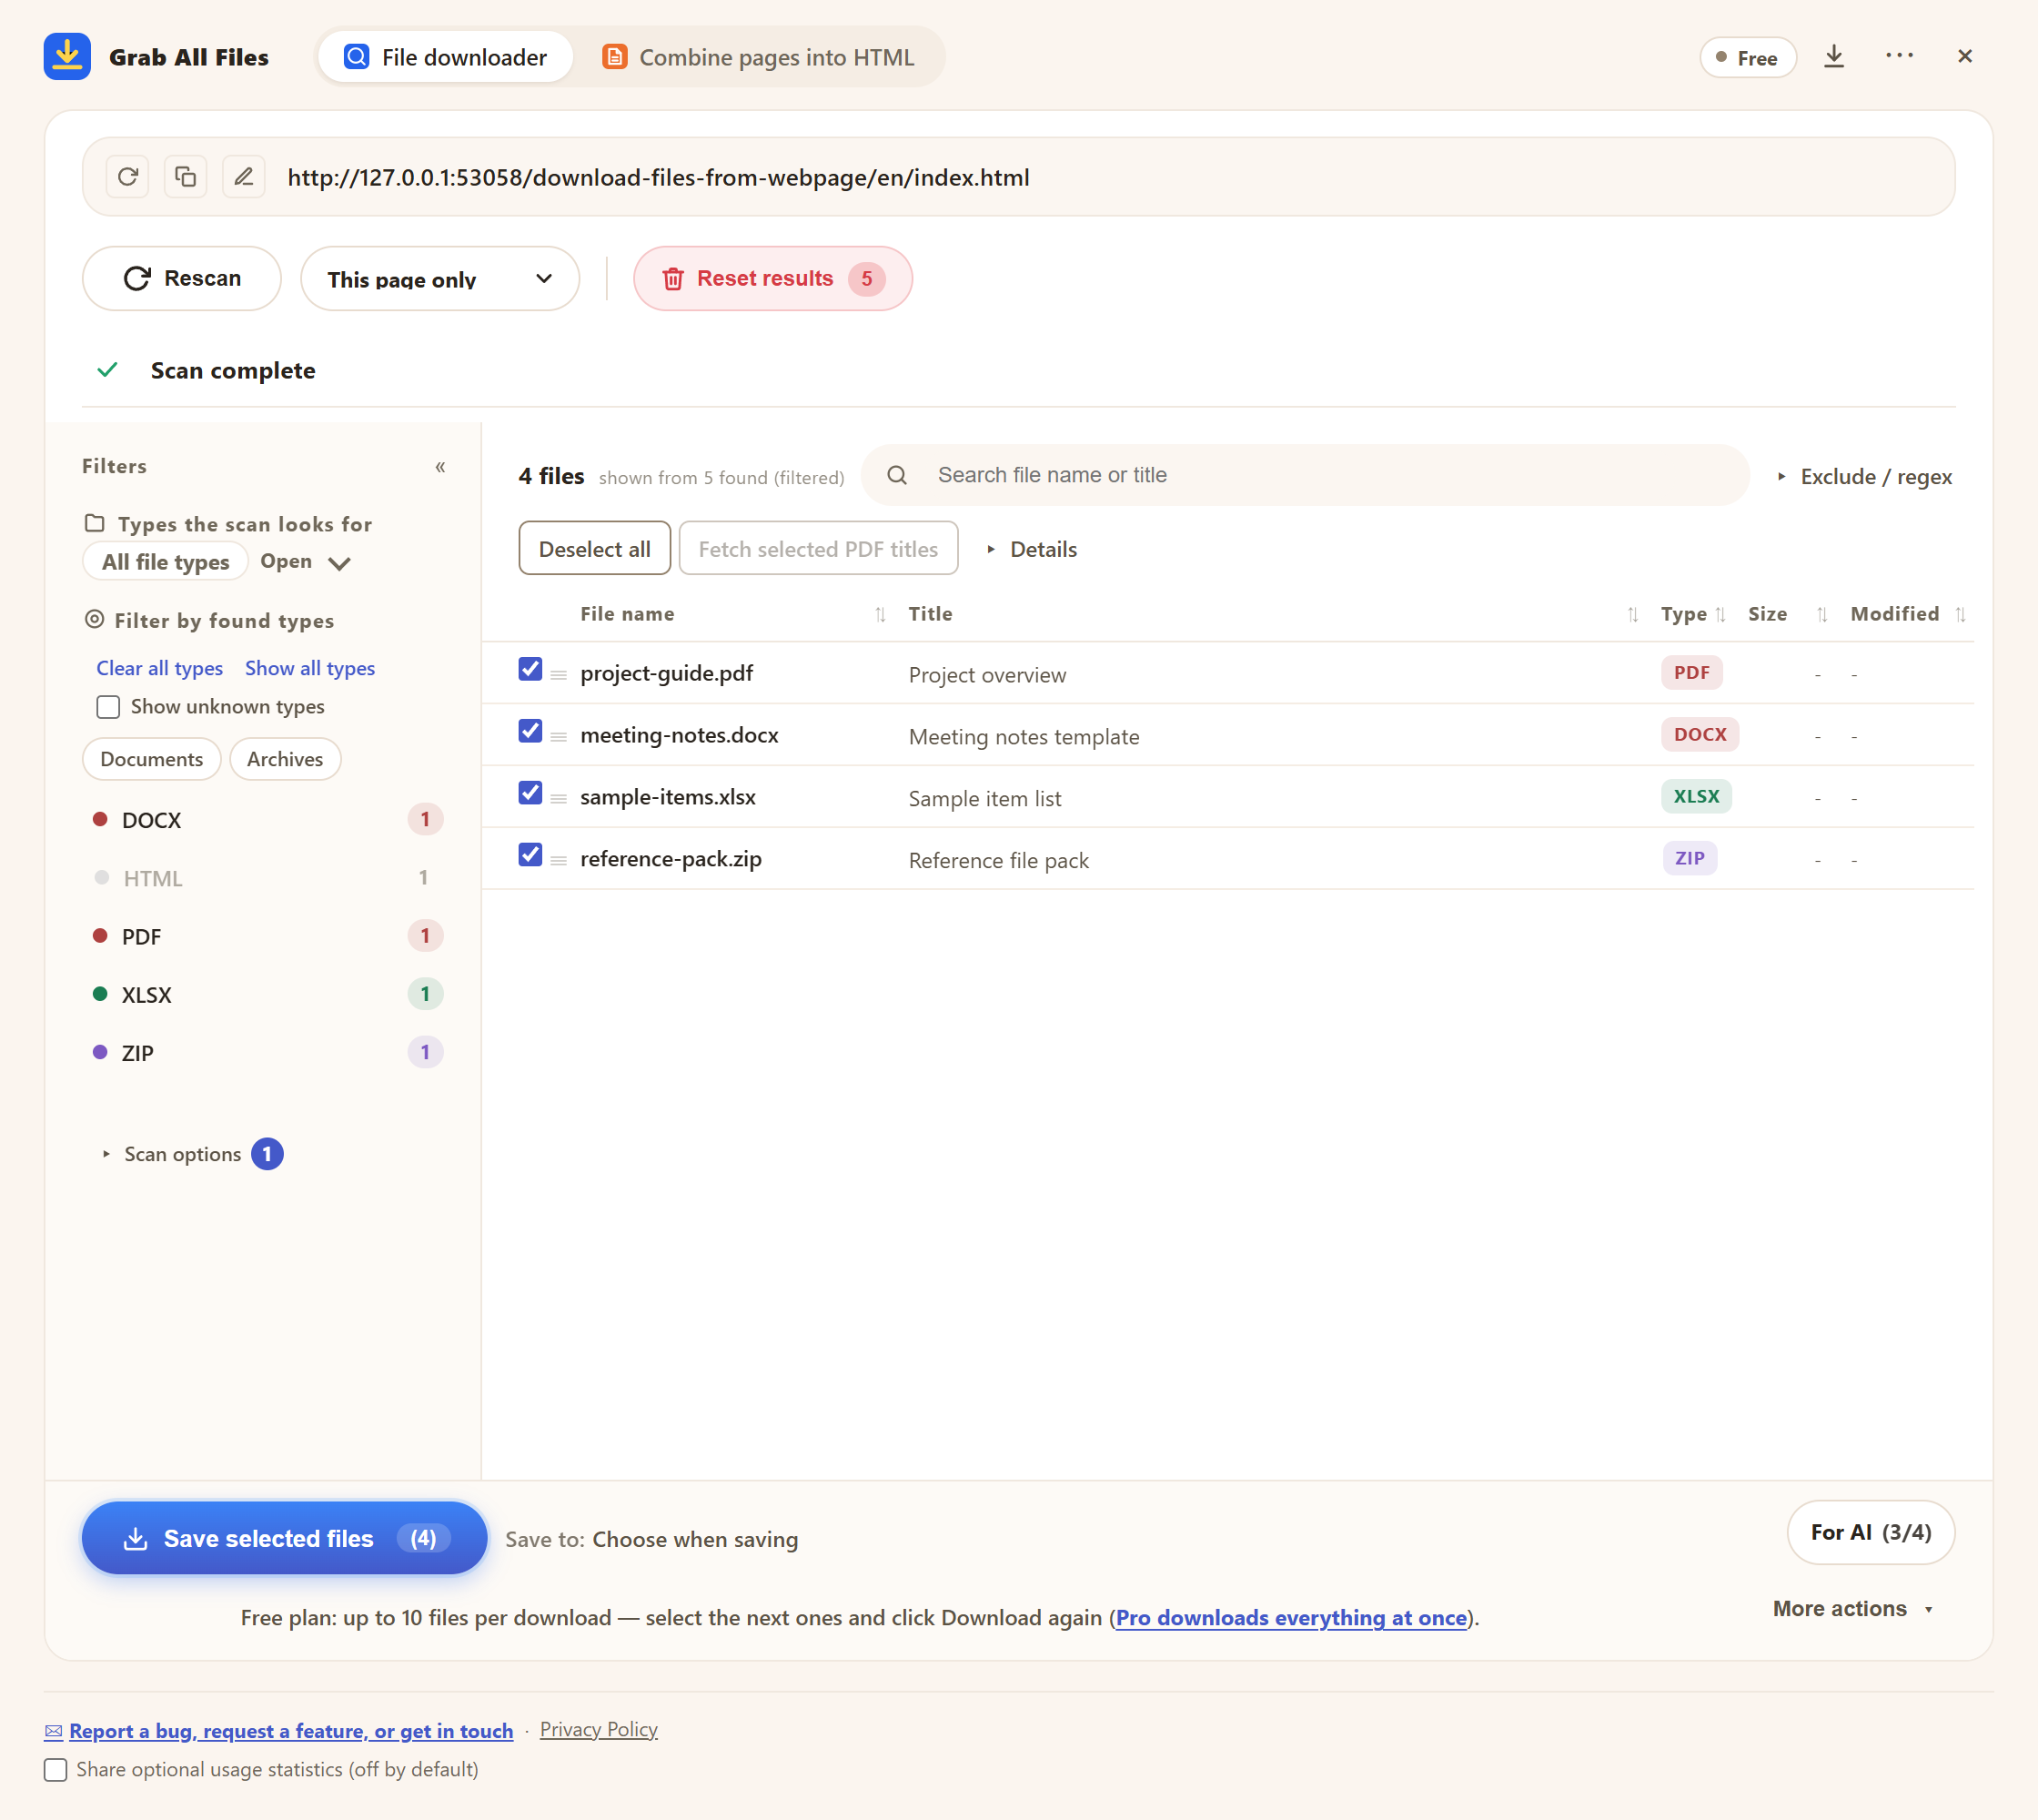
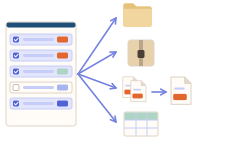
Actual extension screen using sample materials. Selecting supported files on a sample page.
Open the full-size image ↗How the file downloader works
Best for
- ✓Pages with many document, media or archive links.
- ✓Pages where files appear through JavaScript, viewers or background requests.
- ✓Audits that need a CSV of file URLs, sizes and source pages.
- ✓One-off collection jobs where setting up a crawler is too much.
Workflow
- 1Open the page in Chrome, Edge or Firefox and click the Grab All Files icon in the toolbar. The file list is built for the page you are on.
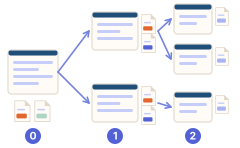
- 2Press “Scan”. To include pages this one links to, raise “Depth” first (“This page only” checks just this page); linked pages are followed only inside the starting page’s folder.
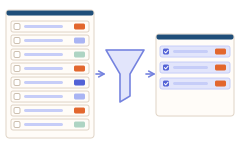
- 3Narrow the list with the file-type list, the search box for names and titles, and “Details” (minimum size, “Save as”). Tick the files you want.
- 4Press “Save selected files”. ZIP, “Merge PDFs”, “Organize” and “Export File Info CSV” are under “More actions”. Free saves up to 10 files per download.
- 5For a longer list, select the next files and press “Save selected files” again. Failed rows show a reason; fix access and retry them.
FAQ
What file types are supported?
PDF, Office documents, images, ZIP, CSV, and many other downloadable file responses can be detected when the browser can access them. It also detects split / multi-volume archive sets such as .001, .r00, and .z01.
Can I choose only certain files?
Yes. Filter by file type, name, title or size, sort by any column and tick only the rows you want. Nothing is saved until you press a save button.
Is there a limit in the free version?
Free saves up to 10 selected files per download, and the same limit applies to ZIP, “Merge PDFs” and CSV export. Select the next files and press the button again to carry on. Pro ($19.99 one-time, up to 3 devices) has no per-download limit.
It found nothing, or fewer files than expected. What can I try?
With Pro, the scan scrolls the page to the end by itself and also follows the next pages of the same list (up to 100 pages per scan). On the free plan the scan reads only what is on screen, so scroll to the end yourself (or open the next page), then scan again. If the files sit on linked pages, raise “Depth”. Pause ad blockers for the site. When downloads are started by the page’s own JavaScript, use “Active Capture” when it is offered.
The page needs a sign-in. What should I do?
Sign in to the site in the same browser first, then scan. Grab All Files uses the session you already have; with Depth 1 or more it opens linked pages with that sign-in. It never signs in for you or bypasses access limits. Rows marked “Login required to access this file” need a fresh sign-in before you retry them.
Does it work on old HTTP pages?
Yes. It can scan both HTTP and HTTPS pages that your browser can open.
Related use-case guides
Try Grab All Files on your browser.
Free saves up to 10 files per download in the file downloader, and one chosen page per run when you combine pages into HTML; that page’s linked files are saved 10 at a time with “Save the next 10”. Pro ($19.99 one-time, up to 3 devices) removes the per-download cap and combines multiple pages into one HTML.