Select the PDFs you need and save them together.
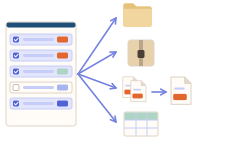
Scan a web page to list its PDFs, check each title, URL and source page, and save only the ones you need. Free saves up to 10 files per download; select the next PDFs and save again to continue. What can be found depends on how the page is built and what you have access to.
Free: up to 10 files per download. Pro ($19.99, one-time) saves them all in one run. What can be found depends on the page and your access.
Real output samples
Files actually saved by Grab All Files 5.8.31 from fictional pages hosted on this site, with the settings used and each file’s hash. Free samples come from the released build; Pro samples from a developer build of the same source.
Download all PDFs in the extension
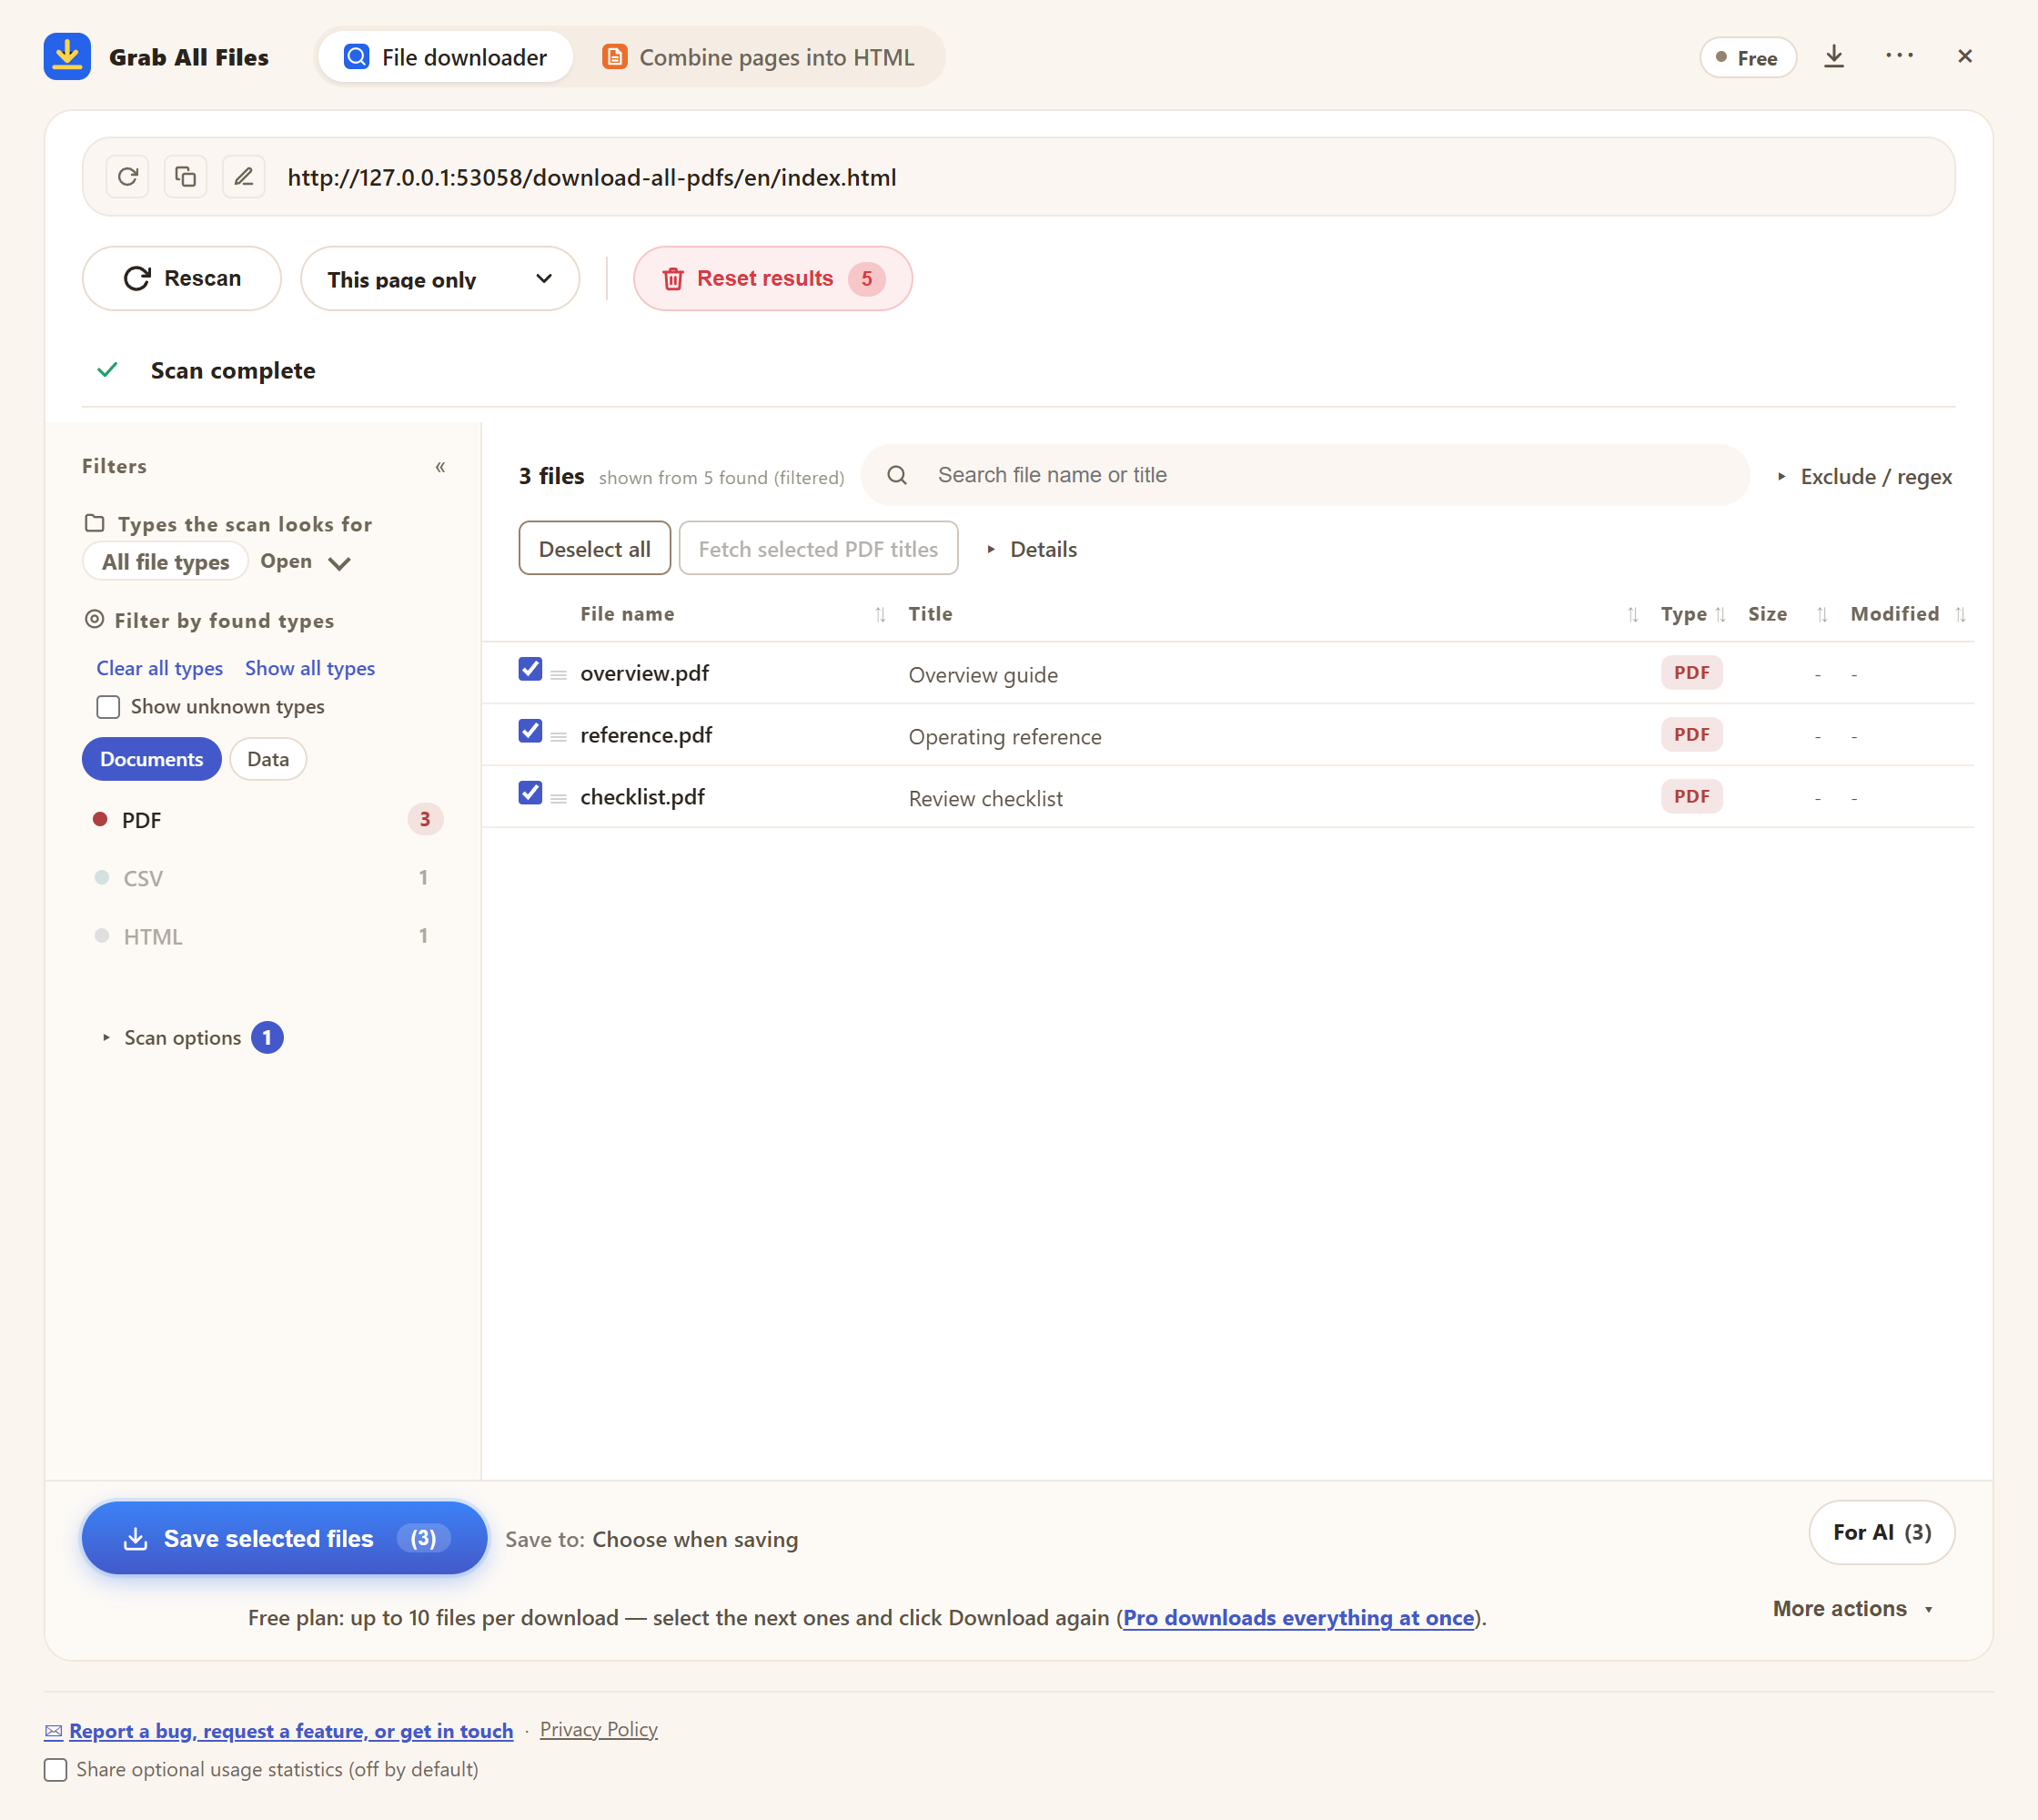
Actual extension screen using sample materials. PDF filtering and selection on a sample page.
Open the full-size image ↗How the file downloader works
Best for
- ✓Public reports, forms, and disclosures spread across multiple pages.
- ✓Course materials, papers, and research PDFs on faculty sites.
- ✓PDF viewer pages where the direct file URL is hidden.
- ✓Course or archive folders where PDFs sit one or two links deep.
Workflow
- 1Open the page that lists the PDFs and click the Grab All Files icon in the toolbar.
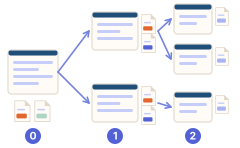
- 2Choose “Depth”, then press “Scan”. “This page only” checks just this page; Depth 1 also scans the pages it links to inside the starting page’s folder, Depth 2 goes one level further. Deeper scans take longer (up to 100,000 pages).
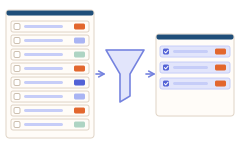
- 3Filter the list to PDF and check the title, source page, size and URL of each file. Tick the PDFs you need.
- 4Press “Save selected files”, or open “More actions” for ZIP or “Merge PDFs”. Free saves up to 10 PDFs per action; tick the next ones and press the button again.
Guides for nearby tasks
- Download files from a pageOffice files, images, ZIPs and other file types as well
- Rename & organize PDF downloadsTidier file names and folders for saved PDFs
- Merge PDFs locallyChosen PDFs combined into one PDF (a separate action from saving)
FAQ
Can it find PDFs inside viewers or iframes?
Yes. It checks iframe sources, viewer URLs, fetch/XHR responses, blob URLs, and common CMS routes where the direct PDF link is not visible.
Can it crawl more than one page?
Yes. Increase the link depth to scan linked pages within the starting page’s folder. For example, /~name/course.html stays within /~name/. Pages outside that folder are not crawled.
Are PDFs uploaded for merging?
No. PDF merge runs locally in your browser.
Can I download PDFs for free?
Yes. Free saves up to 10 selected PDFs per download, ZIP or merge. Tick the next PDFs and press the button again to carry on. Pro ($19.99 one-time, up to 3 devices) removes the per-action limit.
Does it guarantee every PDF will be saved?
No. Results depend on the links found, scan depth, site access and browser support. Review failed downloads, retry them or export the failed URLs with their reasons. The extension does not bypass login or site restrictions.
What if the PDFs are behind a sign-in?
Sign in to the site in the same browser before scanning; the scan and the Depth crawl use that session. If a link returns a sign-in page instead of a PDF, the session has probably expired — sign in again and retry. The extension never signs in for you or bypasses access limits.
Related use-case guides
Try Grab All Files on your browser.
Free saves up to 10 files per download in the file downloader, and one chosen page per run when you combine pages into HTML; that page’s linked files are saved 10 at a time with “Save the next 10”. Pro ($19.99 one-time, up to 3 devices) removes the per-download cap and combines multiple pages into one HTML.